Si Yuan Lee — Software Engineer, ML Infrastructure

Building the training & serving infrastructure behind recommendation at ByteDance.

Prev. Meta · JPMorgan Chase · Thales

Fast models, built to scale

I build the infrastructure that trains and serves recommendation models at scale — from attention kernels to the frameworks and systems around them. Today at ByteDance; before that Meta's Reels AI, JPMorgan Chase and Thales.

Results in production
Sparse MoE optimisation
+23.3%
Throughput, 8B fine-ranking model
+15.36%
Faster SDPA attention kernels
+33%
Inference QPS, 16B MoE model
+20%

Selected Work

Experience

01/ 04NowJuly 2026 - Present

ByteDance

Machine Learning Engineer

Part of AML frameworks team. Focused on ML infra which is the core part of recommendation, ads and search direction. Optimised Sparse MoE by +23.3%, increasing throughput of 8B fine ranking model by +15.36%. Optimised flash_attn_varlen_backward, increasing throughput by +4.84% for the same model.
PyTorchTritonCuteDSLCudaVisit
02/ 04Feb 2026 - Jun 2026

Meta

Machine Learning Engineer

Part of Facebook Reels AI Foundation Team. Form the core AI logic of large-scale recommendation. Dabbled with ML training and experiments for different expert and foundational models. Improved Attention Kernels (fwd and bwd sdpa kernels) by > 33% resulting in training improvement > 5% qps. Implemented blockwise optimisation of SwigLU on MoE, resulting in 30% efficiency gain for SwigLU MoE, improving inference qps of 16B OneFlow model by 20% from 1490 QPS to 1790 QPS.

PyTorchTritonMCPLLMVisit
03/ 04Jun 2025 - Aug 2025

JPMorgan Chase

Software Engineer Intern

Built an Agentic RAG tool that automated 30% of SQL query construction for post-trade regulatory reporting. Remodelled the LLM Suite API with FastAPI, driving adoption across 5 global teams, and engineered metadata-driven vector DB switching that cut p95 retrieval latency from 6s to 2s.

Agentic RAGAIPythonFastAPIVisit
04/ 04Nov 2024 - Jan 2025

Thales

Software Engineer Intern

Designed a PEFT fine-tuning pipeline on AWS EC2 for TinyLlama, StabilityAI, and Qwen models. Achieved a perplexity drop from 16 to 4 for Java Card code completion, with the fine-tuned model passing 90% of regex test cases versus 0% at baseline.

PythonCloudGPUsPEFTVisit
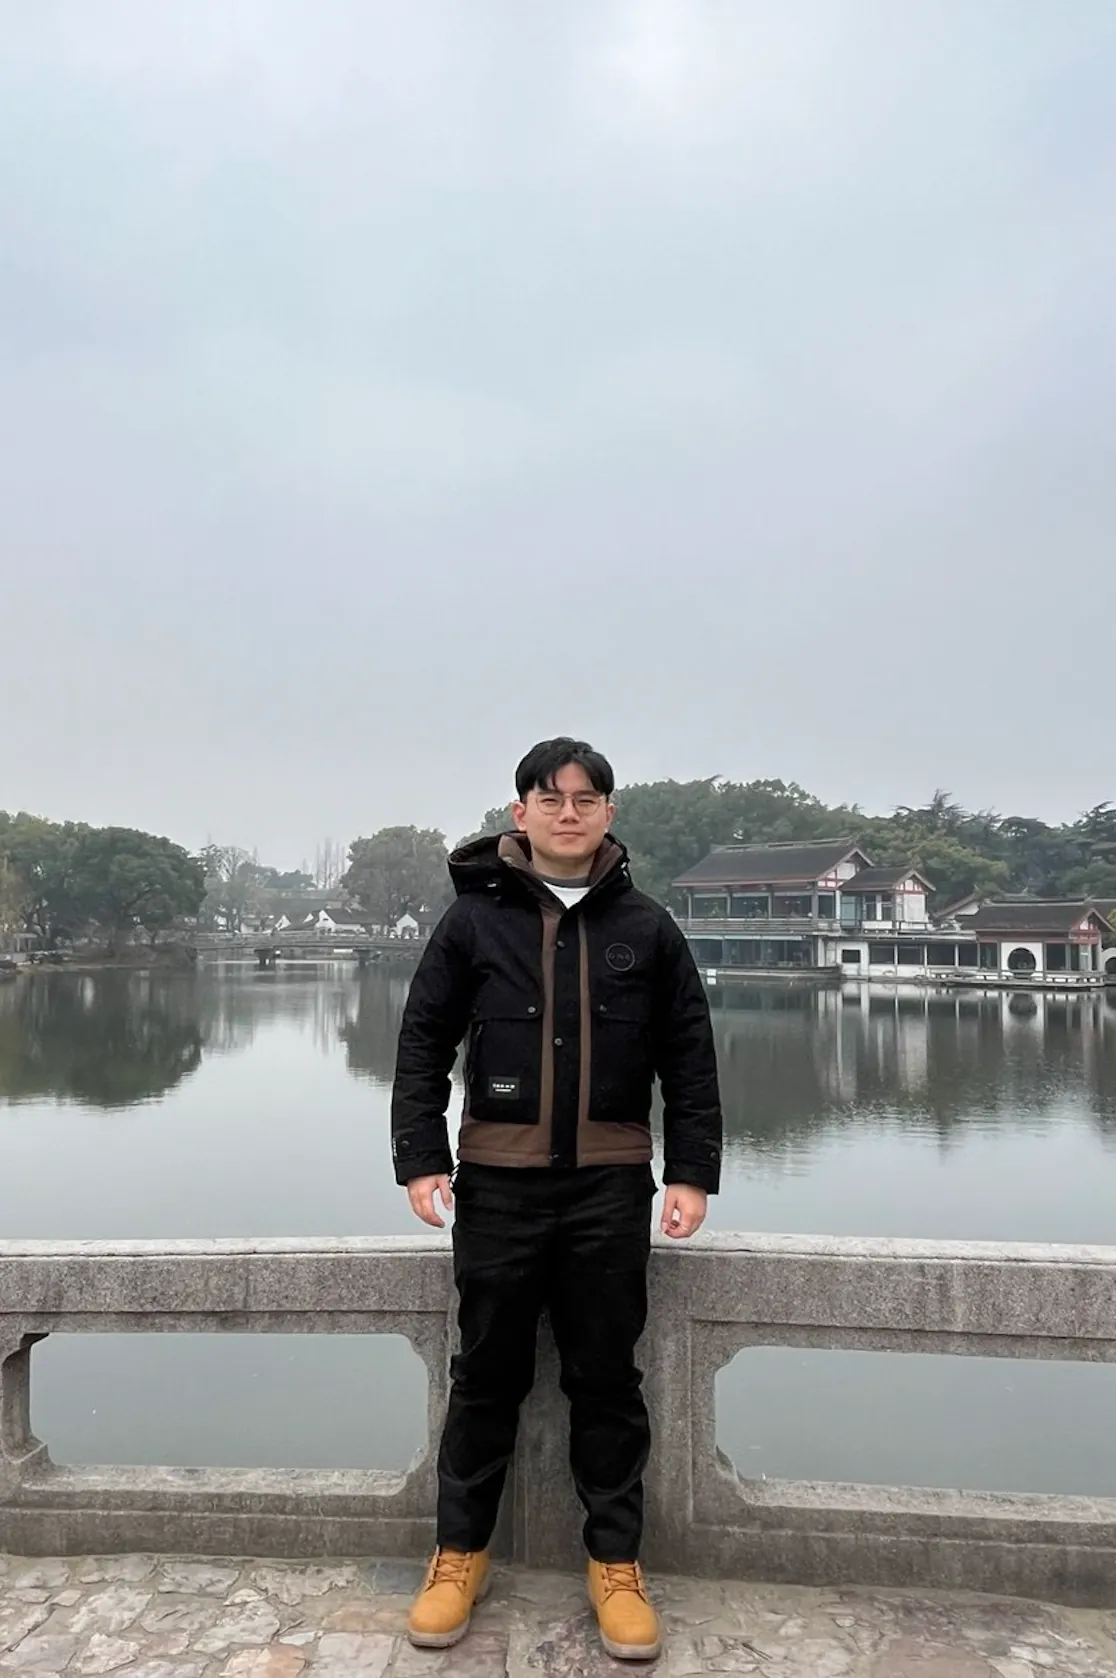
Portrait of Si Yuan Lee

§ 3 — About

Between a model that works and a model that ships, there's a lot of systems work. That's the part I do: kernels, frameworks and pipelines, tuned for scale.

Now

  • ByteDance
  • Machine Learning Engineer, AML Frameworks
  • Since Jul 2026

Focus

  • PyTorch
  • Triton
  • CUDA
  • C++
  • Python
  • TypeScript
  • Go
  • Docker

Off-screen

  • International chess
  • Problem solving
  • Building side projects

National University of Singapore — School of Computing

§ 4 — Contact

Let's talk

Open to conversations about ML systems, infrastructure and ambitious side projects.